Why Databases Need a Write-Ahead Log
The deceptively simple question 'why not just write directly to your data files?' answered by building a write-ahead log from scratch in Rust.
Why Databases Need a Write-Ahead Log
Here's a question that sounds almost too simple to be interesting: why don't databases just write your data directly to wherever it's supposed to live on disk? Why does nearly every serious database (Postgres, MySQL, SQLite, RocksDB, Cassandra) insert an extra step in between, appending to a separate log first, before the "real" write happens at all?
I ran into this directly while building VellumDB, a small LSM-tree key-value store in Rust. The write-ahead log was the very first piece of persistence I added, before there was a memtable, before there were SSTables, before any of the storage structure existed. It turns out that ordering isn't a coincidence, the WAL isn't one feature among several, it's the thing that makes trusting an in-memory data structure possible at all.
The problem it's solving
Say you didn't have a WAL, and a write just went straight to your real, on-disk data structure, whatever that is: a sorted file, a B-tree page, an index. Two things are now true at once, and they conflict.
Writes need to be durable quickly. The moment your code tells the caller "this write succeeded," it has to actually be true, even if the power goes out one instruction later.
Good on-disk structures are expensive to update in small pieces. A sorted file, a B-tree, an index, all of these get their read performance by keeping data organized. Keeping something organized while modifying it one key at a time, safely, with every single change durable before moving on, is slow. That's true regardless of which language or database you're using, it's a property of the storage structure, not the implementation.
So you're stuck: make every write wait for a safe, careful update to a complex structure (slow), or skip the safety and risk corruption or data loss on a crash (fast but wrong). A write-ahead log is how you get out of that trap without picking either side.
The trick: be dumb on purpose
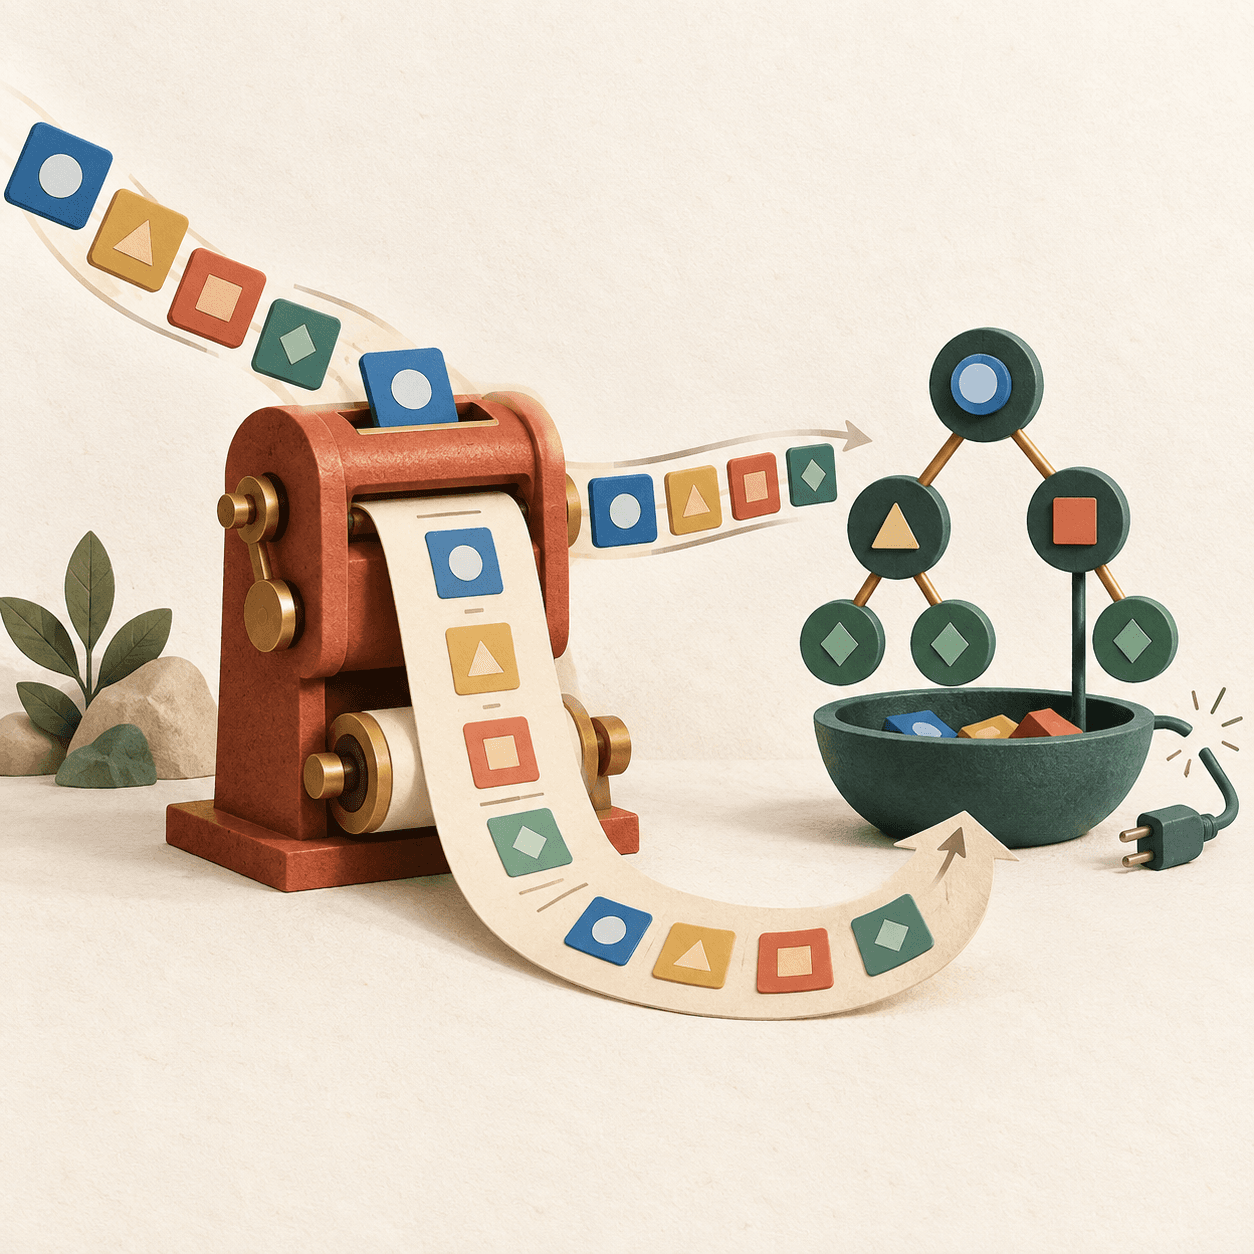
A WAL doesn't try to be a good long-term storage format. It's not sorted, it's not indexed, it doesn't know what a key range is. It does exactly one thing: append raw bytes to the end of a file, in the order they arrived.
pub fn append(&mut self, seq: u64, ops: &[WalOp]) -> io::Result<()> {
    let mut payload = Vec::new();
    // ...serialize the operation...
    write_frame(&mut self.file, &payload)?;
    self.file.sync_data()
}
That's the entire insight. Appending to the end of a file is the cheapest possible disk operation there is, it never has to read anything first, never has to shift existing bytes, never has to reorganize. And because the only job of this file is "prove this write happened," it doesn't need to be sorted or structured at all, it just needs to be complete and checksummed, so that reading it back later in the same order reconstructs exactly what was written.
The actual, well-organized data structure, whatever a given database uses (VellumDB's memtable, a B-tree's pages, an LSM engine's SSTables) gets updated too, but in memory, where doing it carefully and correctly costs nothing close to what a disk write costs. If the process crashes right after that in-memory update but before it's been safely persisted elsewhere, it doesn't matter, the WAL already has a durable, complete record of the operation, and replaying it on the next startup rebuilds exactly the same in-memory state.
fsync is the part that actually matters
Appending bytes to a file isn't durable by itself, not unless you also force the OS to actually write them to the disk rather than leaving them buffered in RAM (the page cache), which is where a write() call normally leaves them for performance reasons. That's what fsync (sync_data in Rust) does, and it's called after every single append:
write_frame(&mut self.file, &payload)?;
self.file.sync_data()
I've written elsewhere about the lengths I went to prove this actually holds up, deliberately killing the process mid-write, corrupting records by hand, simulating torn writes, that's a longer story on its own. The short version here: a write only counts as durable once fsync returns, and every write in VellumDB waits for exactly that before telling the caller it succeeded.
This is also, not coincidentally, the reason a WAL-backed write has a real, measurable latency cost. fsync is orders of magnitude slower than a RAM write, and it shows up directly in benchmarks: write latency around 2 milliseconds per operation, dominated almost entirely by that one call, versus reads that complete in microseconds. That's not a bug to optimize away, it's the actual price of the guarantee. A database that claims to be durable without paying some version of this cost isn't being honest about what it's doing.
What this actually buys you
Once writes are durable in the WAL first, the in-memory structure sitting on top of it is free to be as fast and as simple as you want, because it no longer has to be trustworthy on its own. It can be a plain BTreeMap. It can be entirely unindexed. It can even be thrown away and rebuilt from scratch, because the WAL is what makes rebuilding it possible:
let mut data = BTreeMap::new();
for record in Wal::replay(&wal_path)? {
    // reapply every operation, in order, to rebuild exactly
    // what was in memory before the crash
}
This is the piece that made the rest of VellumDB's design make sense to me. The memtable being an in-memory BTreeMap, something I've written about separately, only works because it doesn't have to solve durability itself. That job already belongs to the WAL. Every layer built on top (the memtable, the SSTables it flushes to, compaction merging them later) gets to assume "whatever was durably written will still be here after a crash" and never has to re-litigate that assumption on its own.
It's not really a database-specific idea
Once you notice the pattern, it shows up everywhere that isn't a database at all. Filesystems call the same idea journaling. Git's reflog is functionally a write-ahead log for your branch history. Distributed consensus systems like Raft are built around a replicated log as the actual source of truth, with everything else derived from replaying it. The common thread in all of these is the same one: durability is cheap and fast if you're willing to be "dumb" about the format (just append, in order), and expensive if you insist the complex structure be perfectly safe to update directly on every single write.
The full WAL implementation, along with the crash and corruption experiments that tested whether the durability claim actually holds, is on GitHub if you want to see how it fits into the rest of the engine.